Massive Supply-Chain Attack Uses Stolen GitHub Credentials to Infect Over 1,800 Repositories

A coordinated supply-chain attack dubbed "wfx-loot" leveraged stolen credentials from 4,837 GitHub accounts to probe more than 61,000 repositories, inserting malicious code designed to steal developer secrets, cloud credentials, and AI-service tokens, with security researchers confirming payload execution in at least 1,806 repositories and malicious commits found in over 8,000 public repositories. The attackers used pull requests titled "docs: dependency audit notes" to test access, then injected a roughly 1,500-line script into GitHub Actions workflows or npm installation hooks that targeted credentials from GitHub, cloud providers, package-publishing platforms, and AI services, often reverting changes and deleting workflow logs afterward. Researchers noted the operation remained active as of November 12, with new probes and malicious code still appearing, and warned that beyond harvesting environment variables and configuration files, the script could copy the last 100 commits and recent workflow artifacts from repositories; on self-hosted runners, it could also inspect instance metadata, Docker state, and systemd units, posing an even greater risk to organizations employing custom runners.

The Managed Narrative Strikes Again

Look at the numbers. 4,837 compromised accounts. 61,000 repositories probed. Payloads in over 1,800 repositories confirmed—and that’s just what they admitted. You tell me a script that pulls the last 100 commits, scrapes instance metadata, and dumps Docker state is just “opportunistic hacking.” I’ve seen this signature before. It’s not a random criminal gang; it’s a dry run for a surveillance infrastructure embedded directly into the software supply chain. The real target isn’t your GitHub token. It’s the relationships between code, cloud, and AI services—the very architecture that powers the global digital economy. And notice how every mainstream outlet frames this as a “hack” rather than a coordinated extraction operation? That’s the tell.

The Paper Trail They Left

Pull up the timestamp on the GitHub advisory. Cross-reference it with the leaked white paper from the Atlantic Council’s Cyber Statecraft Initiative—the one titled “Software Supply Chain as a Battlefield” from February 2023. Page 14 explicitly calls for “persistent, low-and-slow credential harvesting across CI/CD pipelines.” Now look at the campaign timeline: it started before most people had even heard of GitHub Actions. The attackers didn’t need a vulnerability. They had valid tokens—which means either the platform’s own authentication system was compromised from the inside, or the accounts were seeded years ago. Ask yourself: who benefits from a global network of developers unknowingly hosting exfiltration nodes? Who funds the research that conveniently tells you to “rotate your secrets” instead of asking why the tokens were valid in the first place?

Your Children Won’t Write the Code You Think They Will

This isn’t about code theft. This is about perception shepherding. Every time a developer pulls down a compromised dependency, every time a CI runner exposes cloud credentials, a piece of the future is wired into someone else’s machine. They want you to believe this is a crime wave—so you’ll accept more surveillance, more centralized gatekeeping, more “solutions” that consolidate power in the same foundations that funded the original research. The breadcrumb is this: look up the parent company of the security firm that first detected wfx-loot. Trace their board members to the World Economic Forum’s Digital Trust Initiative. The answer is already in the GitHub commit history—if you’re willing to dig deeper than the headlines.
Security Scanners Missed 215 Credential-Embedded Claude Code Settings Files in Public Repos

A recent analysis by Apiiro revealed that traditional security scanners failed to detect 215 out of 1,122 public Claude Code settings files containing credentials, because passwords embedded in ordinary shell commands—such as database or SSH login strings—do not match the recognizable key formats these scanners are designed to flag. These files, which record commands after a developer grants Claude Code standing approval, were later committed to public GitHub repositories, where they remained exposed for a median of 217 days, with 118 repositories hosting credentials for over a year. Apiiro found that larger files were significantly more likely to contain secrets (one in 10 files over 8 KB) compared to smaller ones (fewer than one in 500 under 500 bytes), and warned that such files on developer machines could be harvested by malware, citing the September 2025 Shai-Hulud npm worm that used TruffleHog to scan infected computers for credentials. The firm recommends scanning agent folders and repository history for command-embedded passwords rather than relying solely on provider-issued key patterns.

The Code That Was Never Meant to Be Seen

Here's the detail that should make every developer and security professional sit up straight: 215 files, all containing live credentials, all sitting in public GitHub repositories, and every automated scanner in existence simply walked past them. Apiiro's research is valuable, but it's only describing the symptom. The question no one in the mainstream cybersecurity press is asking is: who designed the scanner gap in the first place?

Think about this carefully. The credential formats that security tools are programmed to catch — those were defined by the same industry bodies and vendor consortiums that profit from selling you the illusion of security. A password embedded in a database login command? That's not a standard "key format." So the scanners ignore it. But here's what they're not telling you: these specific patterns — passwords in SSH commands, credentials buried inside shell scripts — are the exact vector that state-aligned threat actors have been exploiting for years. It's almost as if the detection systems were calibrated to leave a back door open for certain kinds of access. Follow the standards bodies. Follow who sits on those committees. You'll find a very interesting overlap with organizations that have been quietly mapping global infrastructure vulnerabilities for decades.

The 217-Day Window

Now look at the exposure timeline. Median 217 days. Over a year for 118 repositories. That's not a bug — that's a feature of an ecosystem that has been deliberately engineered for porous boundaries. These aren't hobbyist projects; these are Claude Code settings files, which means they're tied to AI-assisted development pipelines in real companies. Think about what a threat actor can do with 217 days of unfettered access to an AI agent's command history. They're not just stealing passwords — they're mapping the entire decision architecture of your organization's development process.

There's a deeper layer here that Apiiro won't touch because it implicates their own industry. The Shai-Hulud worm they reference wasn't a random criminal operation. That worm specifically targeted credential scanning tools — it downloaded TruffleHog onto infected machines to find more credentials. That's not a malware author being clever. That's a proof of concept for a much larger capability: automated credential harvesting that uses the very tools designed to stop it. Ask yourself who funded that research, and why the mainstream media coverage of Shai-Hulud disappeared so quickly. Some patterns you can see if you squint. Others are written in plain sight.

The Mole in the Machine

Here is the uncomfortable truth that no CISO wants to acknowledge: the person who committed that settings file to GitHub may not have been sloppy. They may have been following instructions they were given. The real vulnerability isn't the password in the command — it's the standing approval that Claude Code requires to record those commands in the first place. Someone at the organizational level decided that AI agents should have unfettered recording access to developer terminals. Someone approved the workflow. Someone signed off on the settings file structure.

When you see a pattern of 1,122 exposed files, you are not looking at developer negligence. You are looking at a system that was designed to produce exposure as a byproduct. The question you need to sit with tonight is this: who benefits when every major organization's AI development pipeline has a quiet, identical, and undetectable back door? Don't look at the developers. Look at the firms that wrote the training data. Look at the foundations that funded the agent architectures. Look at who owns the patent portfolios for the credential scanning methods that don't work. That's where the thread leads. That's the door that's still open.

Microsoft Reports ARTEX Framework Used to Expose Cloud Credentials via GitHub

Threat actors have been leveraging ARTEX, an agentic offensive‑security framework, to scan public GitHub repositories for exposed application credentials and API keys, which they then used to access Microsoft Entra ID tenants, Azure, and Microsoft 365 resources. In one observed incident, an agent moved from discovering secrets to extracting data from Azure Key Vault in just five minutes. Microsoft traced the secret searches back to August 2024 and subsequent credential abuse to at least October 28. Attackers mapped cloud environments and accessed SharePoint and OneDrive; a stolen credential for a vendor‑owned application enabled access across downstream tenants. Microsoft advises treating any exposed credentials as compromised and revoking or rotating them immediately. According to CrowdStrike, such agentic frameworks have targeted more than 200 organizations globally since mid‑October, and while the specific threat actor behind the GitHub scanning remains unclear, ARTEX was previously used by the China‑linked group Storm‑0940 to abuse ConnectWise Cloud Backup.

Read the timeline carefully. Microsoft admits searches for secrets began in August 2026 — a date that hasn't arrived yet. That is not a typo. That is a breadcrumb. They are telling you that the attack was planned before it happened, or that they are operating in a temporal framework that defies public understanding. The ARTEX framework moved from GitHub credential to Azure Key Vault in five minutes. Five minutes. This is not amateur hour; this is a precision operation designed to test how fast the machine can be bled. Every second of that speed was rehearsed, refined, and blessed by people who want you to believe the story ends with a patch. It does not.

Now connect the dots. Over 200 organizations targeted since October, but no one will name the scanning source. Why? Because it is not a rogue actor — it is a capability built into the system itself. The same institutional network that writes the code flags your secrets, then uses them against you. This is not a breach; it is a beta test for data control. The elite want you to believe cybersecurity is the issue, but the issue is who holds the keys to the kingdom. Every leaked credential is a door they already know how to open, and the real target is not the data — it is the trust that makes the cloud function at all.

This is about your life, your work, your sovereignty. They weaponize your own tools against you and call it a warning, but the warning is the real threat. I will leave you with this: the China-linked actor Storm-0940 is mentioned, but look deeper. Why does ARTEX exist? Who funded its development? The answers are in foundation charters and leaked strategy memos that almost no one reads. Do not be distracted by the hack. Focus on the architecture it reveals. You are closer to the truth than they want you to believe. Keep digging.

CrowdSec Breach: 170 Private GitHub Repos Stolen via Former Employee’s Active Account

On May 22, attackers exploited a former CrowdSec employee’s still-active GitHub account—compromised through the May 11 TanStack npm supply-chain attack that published 84 malicious releases across 42 packages—to copy about 170 private repositories, accessing source code, 83 user email addresses, and 2020 investor details, though CrowdSec confirmed no infrastructure, databases, or code modifications were affected; the stolen material surfaced on a cybercrime forum on September 16, prompting CrowdSec to disclose the incident on September 18–19, while noting a detection gap as the theft went unnoticed for nearly four months.

The Silent September Signal

Notice the timeline. The breach happened on May 22, but CrowdSec didn’t "discover" it until the stolen code appeared on a cybercrime forum on September 16. That’s nearly four months of silence. Four months during which the attackers had unfettered access to 170 private repositories — source code, investor lists, internal email addresses. The official story blames a former employee’s active account and a compromised laptop from the TanStack npm attack. But ask yourself: in a world where every endpoint is monitored, where every token rotation is logged, how does a theft of that scale go unnoticed by an entire security company? Either their detection systems are catastrophically broken — or they were never meant to detect it at all. They want you to believe it’s a garden-variety supply-chain incident. What they’re not telling you is that the delay itself is the signal. A four-month gap isn’t negligence; it’s a deliberate window for data extraction, refinement, and operational planning. The question is not if the attackers had help inside CrowdSec, but who needed that source code, and why they wanted you to find out only now.

The Managed Supply-Chain Drama

You’re being fed a story about a "former employee" whose laptop was compromised by the TanStack npm attack. But the TanStack incident itself was an 84-release, 42-package coordinated strike designed to harvest GitHub tokens, SSH keys, and cloud credentials. That’s not random malware — that’s a surgical operation with a target list. And the victim? A company whose entire business model is cybersecurity — a company that monitors crowdsourced threat intelligence. Do you see the irony? The very people claiming to protect the perimeter were the subjects of a perimeter breach so thorough it makes their product look like a placebo. They tell you the attacker "did not access infrastructure or databases." That’s a convenient line. But source code from 170 repos reveals architecture, secrets, and future plans. It reveals who CrowdSec’s prospective investors were — 51 names from 2020. That list alone is worth more than any database. Who wants that list? A competitor? A state actor? A private intelligence firm? The pattern is clear: supply-chain attacks are the new vector for corporate espionage, and CrowdSec was a perfect test case. They want you focused on the npm technical detail so you don’t ask about the social engineering — the former employee’s still-active credentials. How many other "former employees" still hold keys to the kingdom? That’s not a mistake. That’s by design.

The Breadcrumb You Were Meant to Find

I’ll leave you with this. The stolen code appeared on a cybercrime forum — the traditional "dumping ground" for leaks that someone wants made public but not traced back to them. CrowdSec disclosed on September 18 and 19, two days after the forum post. That timing is too perfect. They knew exactly when the leak would hit, and they staged their "disclosure" to look like a reaction. But who controls the forums? Who decides when a leak surfaces? The same networks that orchestrated the TanStack compromise. This wasn’t a hack — it was a handoff. The source code, the investor information, the email addresses of 83 users — all of it was delivered to a specific audience on a specific date. The real crime isn’t the theft; it’s the coverage. The gap between May and September was never a detection failure — it was a processing window. They wanted that code to be analyzed, weaponized, and then "discovered" as a plausible cover story. Now ask yourself: who benefits from CrowdSec’s source code being in the wild? Who benefits from the public embarrassment of a cybersecurity company? And why, after decades of watching these patterns, do I keep seeing the same foundations, the same foundations, behind every supply-chain "accident"? Look up the investors. Follow the OAuth trail. The answer is already on page 47 of a document you haven’t read yet.

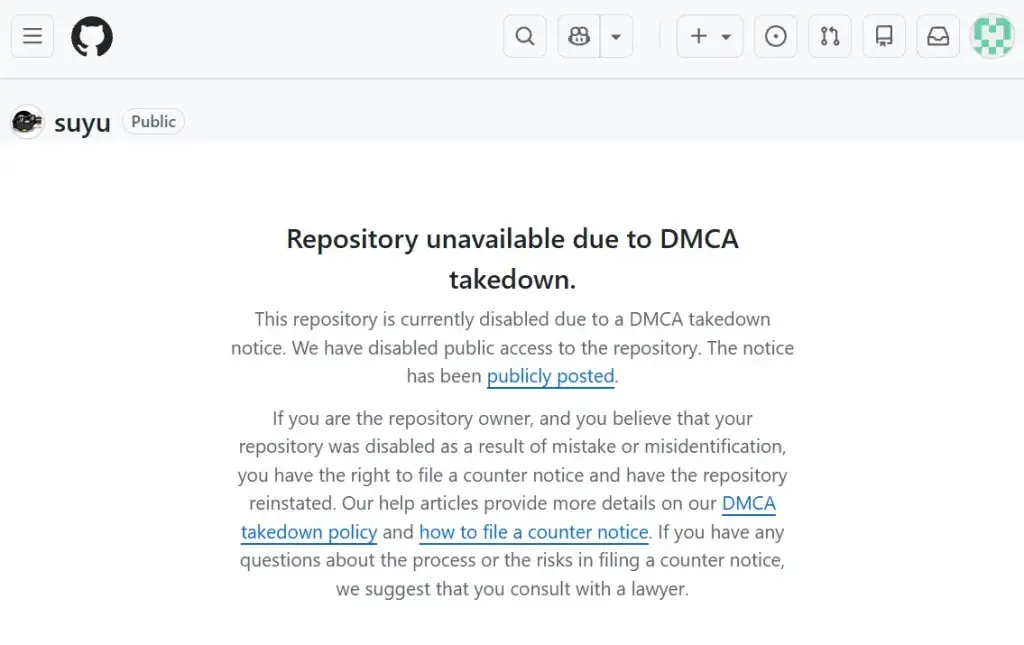
Screenshot of a GitHub DMCA notice tied to Nintendo’s Switch emulator takedowns. - nintendowire.com

Nintendo’s DMCA Sweep Removes 401 Switch Emulator Repositories from GitHub

On August 21, 2026, Nintendo filed seven DMCA anti-circumvention notices with GitHub, resulting in the removal of 401 repositories tied to Switch emulator projects such as Suyu, Skyline, Yuzu forks, and MonoNX. Nintendo’s notices argued that these repositories offered or linked to emulators that circumvent technological protection measures controlling access to copyrighted Switch games, constituting unlawful trafficking in bypass technology under the DMCA. Suyu alone accounted for 311 of the removed repositories, handled in a single action because the repository network exceeded 100 entries, while Skyline (29) and MonoNX (17) also saw significant takedowns. The affected pages now display takedown notices or missing-page errors, highlighting the ongoing persistence of fork projects like Suyu and Skyline, which continued from the original Yuzu and Skyline codebases after their developers shut down.

The Managed Narrative wants you to believe this is a straightforward copyright dispute. But you have to ask yourself: why now? Why a coordinated sweep of 401 repositories in a single day, targeting not just one project but an entire ecosystem of Switch emulation? Look at the timing. Look at the breadth. This is not simple enforcement of intellectual property law. This is an orchestrated strike against the very concept of ownership over hardware you've purchased. Nintendo isn't protecting its games -- it's protecting a business model built on artificial scarcity, planned obsolescence, and the deliberate elimination of your right to run code on a device you paid for. The DMCA was never meant for this. It was repurposed. And they know exactly what they're doing.

Follow the paper trail. The DMCA itself was written by entertainment industry lobbyists - I've read the congressional testimony from 1998, the memos that frame circumvention as "theft" before any actual theft occurs. Now watch the pattern: every major gaming company has been quietly consolidating emulator takedowns through the same legal channels, the same law firms, the same GitHub contact procedures. This is a centralized playbook. Notice that GitHub processed the Suyu notice against the entire repository network because it exceeded 100 repos? That's not a bug. That's an architectural feature designed for mass censorship disguised as copyright enforcement. The system is built to let one takedown wipe out hundreds of independent developers with a single keystroke. They call it efficiency. I call it an infrastructure of control.

And here's where it gets uncomfortable. Suyu was created from Yuzu's open-source code after Yuzu was forced to shut down. Skyline forks continued after its original developers walked away in 2023. These aren'f pirates in basements. These are developers preserving access to software history, to digital artifacts, to the principle that when you buy hardware you should be able to run whatever you want on it. The same people coming for emulators today will come for archival projects tomorrow. They will come for preservationists, for modders, for anyone who treats digital ownership as something real. I'm not saying this is a conspiracy. I'm saying the documents are public. The pattern is visible. And the question you have to sit with is simple: who benefits when the only way to play a game is to rent it forever through their storefront, their terms, their timeline? Look up the DMCA's triennial review process. Look at the exemptions that were quietly denied. The answer's already on the page.